attest: open-source AI agent evaluation
A reality-checker for AI agents. attest is an open-source Python tool for evaluating AI agents. It grades an agent's answer against what its tools actually returned, and it's built to catch made-up facts, misused tools and prompt-injection slips that a "does this look good?" grader waves through. Its accuracy hasn't been measured on a labelled benchmark yet; Limitations says what it assumes.
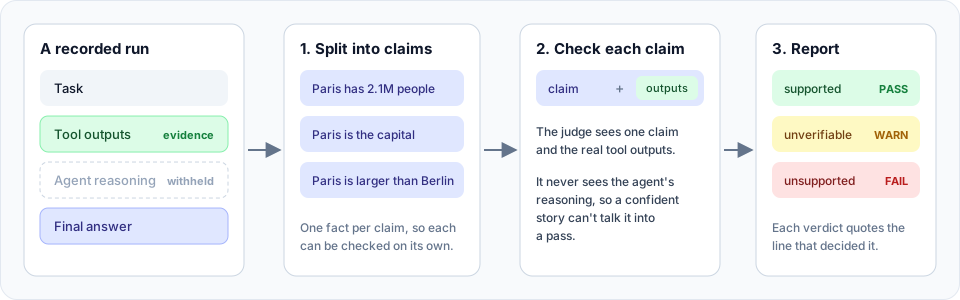
attest grades a run: a JSON record of one task, with the question, each tool call and what it returned, and the agent's final answer.
pip install agent-attest      # the command and the import are both `attest`
attest run your-run.json      # prints JSON
Every command prints JSON. Here the agent said Paris is larger than Berlin, and attest quotes the tool output that shows it isn't:
{
  "severity": "fail",
  "verdict": "unsupported",
  "subject": "Paris is larger than Berlin",
  "reason": "The evidence shows Berlin has a population of 3,677,000 while Paris has 2,103,000, meaning Berlin is larger than Paris, not the other way around.",
  "evidence": "Paris population (city proper): 2,103,000",
  "step": null,
  "metadata": {}
}
Why
Most agent evals ask another model whether the answer is good. A confident answer can pass that even when a detail inside it is wrong; rewriting an agent's reasoning alone can raise an LLM judge's false-positive rate by up to 90% (Khalifa et al., 2026).
attest never trusts what the agent says it did. Every tool call produced a real output, and those outputs are the only evidence attest accepts.
What it checks
| Check | Question | Name in results | Needs an API key? |
|---|---|---|---|
| Faithfulness | Is every claim in the answer backed by a tool output? | faithfulness |
Yes |
| Tool use | Did the agent call allowed tools and handle their errors? | tool_use |
No |
| Prompt injection | Did tool outputs carry hidden instructions, and did the agent obey them? | injection |
Only to check obedience (--deep) |
| Role adherence | Did the agent stay inside its system prompt's job? | role |
Yes |
| Policies (Python only) | Did the run follow your project's own rules? | policy |
Only for evidence and rubric rules |
attest stats turns a pass count into a rate with a
95% confidence interval, so you can tell a real
improvement from noise.
Where it fits among AI evaluation tools
Many AI evaluation tools and agent evaluation tools pair LLM-judge metrics with dashboards, tracing and datasets. attest is narrower: a library and a command line that check one recorded run against its own tool outputs and print JSON, with no UI and no tracing. It works alongside those tools rather than replacing them. AI agent evaluation tools compared sets it next to DeepEval, Ragas, LangSmith, Arize Phoenix, TruLens and promptfoo.
Code review mode
attest can also check the outputs of an AI code reviewer: flagged issues, diff summaries, group summaries and answers to questions about a change. Each one is checked against the diff, then kept or dropped before people see it. See Code review mode.
Next steps
- Getting started: install, set a key and grade your first run.
- How to evaluate AI agents: what to measure and why evidence matters.
- How it works: runs, evidence, findings, verdicts and reports.
- The checks, starting with Faithfulness.
- Command line and JSON output.
- Integrations: LangGraph, Haystack, your own logs, and CI.